MiniMax H3 / Texto para Vídeo
Open-weight general-purpose multimodal video model. Unifies text, image, video, and audio understanding in a single context window, generating up to 2K resolution, 15-second clips with native stereo audio at 24fps. Supports multimodal reference inputs: up to 9 images, 3 videos, and 3 audio clips (12 total references) per generation. Features first-frame, last-frame, and full reference modes with conversational editing capabilities.
MiniMax H35-Mode Cinematic Video with 2K Output
MiniMax H3 is a multimodal video foundation model with five generation modes — text, image, end-frame, start-and-end-frame, and reference conditioning — plus native 2K resolution and up to 15-second clips.
At a Glance
Multimodal Video Architecture
One model for every conditioning path — from pure text to multi-reference cinematography.
Five Conditioning Modes
Text-to-video, image-to-video, end-frame, start-and-end-frame, and multimodal reference-to-video — switch modes without changing providers.
Native 2K Resolution
Ship 768P for drafts and social, or promote hero placements to 2K without a separate upscaler pass.
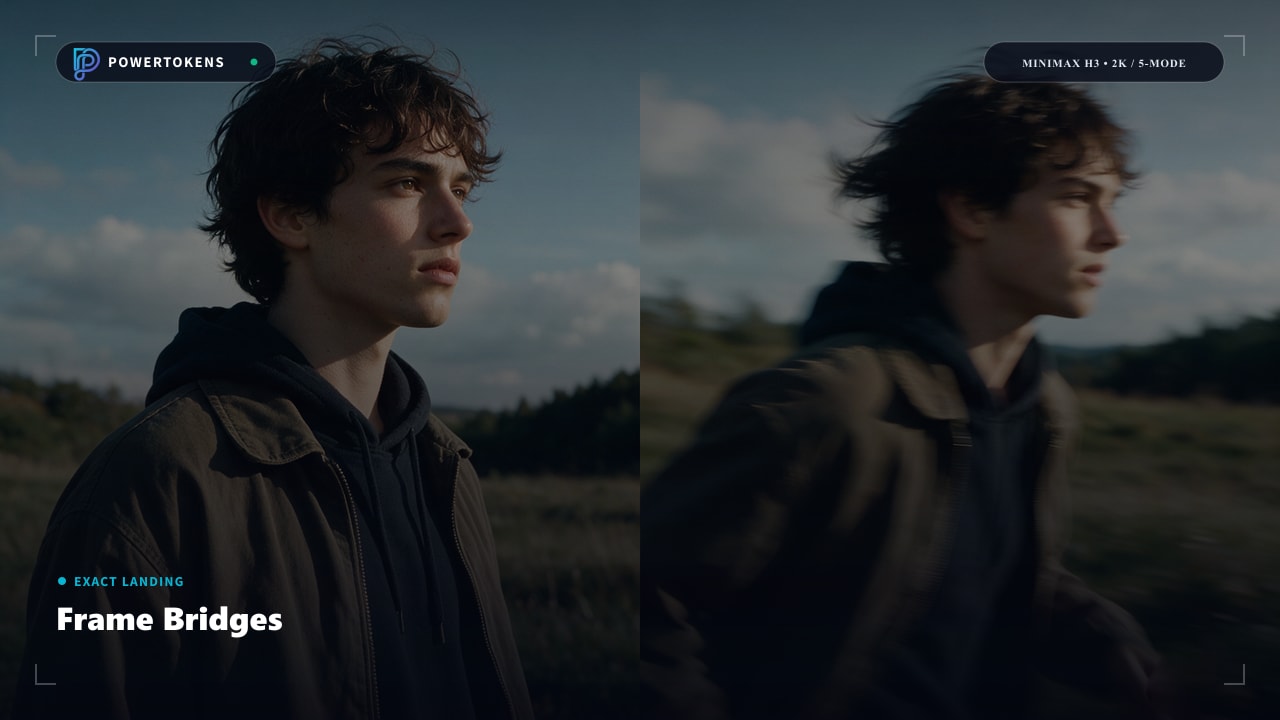
Start & End Frame Bridges
Land exactly on a target end frame for match cuts, product morphs, and seamless scene transitions.
Cinematic Ratio Suite
Text-to-video supports 21:9, 16:9, 4:3, 1:1, 3:4, and 9:16; reference mode also allows adaptive framing.
How It Works
From brief to finished multimodal clip.
Pick a Mode
Start from text, a still, an end frame, both frames, or multimodal references.
Set Canvas & Length
Choose 768P or 2K, aspect ratio, and 4–15 second duration for the placement.
Condition with References
In reference mode, feed stills or motion cues that lock identity and style.
Deliver & Chain
Pull the finished clip and bridge into the next shot with end-frame continuity.
H3 Production Domains
Where multimodal control replaces stitched pipelines.
Brand Film Previs
Reference-conditioned previs before full live-action shoots.
Product Morph Ads
End-frame and dual-frame transitions for packshot reveals.
Ultra-Wide Storytelling
Native 21:9 cinematic boards for hero brand placements.
Social Vertical Cuts
9:16 clips up to 15 seconds for Reels and TikTok.
Prompt & Usage Tips
Get cleaner first-pass H3 generations.
If you need a bridge, mention the end composition in the prompt so the model aims for that landing frame.
Draft at 768P, promote only final hero placements to 2K to control spend.
Reference mode is strongest when each image has a single clear job — identity, style, or scene.
H3 Multimodal Quickstart
Submit text or reference-driven clips with native 2K support.
curl -X POST "https://api.powertokens.ai/v1/videos" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "MiniMax-H3",
  "prompt": "Cinematic tracking shot through a neon cyberpunk city in heavy rain.",
  "seconds": "5",
  "size": "1080p",
  "ratio": "16:9",
  "resolution": "2K",
  "duration": 8
}'
Technical Specifications
Confirmed parameters and runtime execution protocols.
Detalhes de preços
A cobrança real deste modelo é calculada dinamicamente com base nos parâmetros específicos da sua solicitação de API. Abaixo estão as combinações específicas e seus preços correspondentes:
Nota: As primeiras 5 imagens de entrada de cada solicitação são gratuitas. As imagens de entrada subsequentes são cobradas de acordo com o preço de entrada mostrado na tabela.
Regras de faturamento: Tanto o vídeo de entrada quanto o de saída são cobrados por segundo de vídeo.
| Modalidade | Entrada de imagem | Entrada de vídeo | Saída |
|---|---|---|---|
| 768P | $0.040 40/ Image | $0.080 80/ Second | $0.080 80/ Second |
| 2K | $0.040 40/ Image | $0.130 130/ Second | $0.130 130/ Second |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
MiniMax-H3-Max
MiniMax-H3-Max
High-speed video model post-trained by fal.ai on MiniMax H3, optimized for low-latency generation. Ranks #1 in image-to-video (Elo 1,204) and #3 in text-to-video with audio (Elo 1,235) on Artificial Analysis. Generates 5-second 768p video in under 3 seconds (35x throughput vs. H3), enabling real-time streaming, live AI broadcasting, and instant content creation. Supports text-to-video and image-to-video (first/last frame), 5–15s clips, 480p/768p, and native stereo audio
MiniMax Hailuo 2.3 Fast
MiniMax-Hailuo-2.3-Fast
A streamlined AI video model prioritizing speed and cost-efficiency. Generates 6-second 768p videos rapidly with 50% lower batch costs. Maintains solid motion physics and stylization for quick iterations, drafts, and short-form content.
MiniMax Hailuo 2.3
MiniMax-Hailuo-2.3
A flagship AI video model delivering breathtaking motion and lifelike emotion. Excels in fluid character movements, cinematic lighting, and multi-style support (anime, ink wash). Produces 1080p, 6/10-second videos with natural micro-expressions for high-fidelity creative work.
MiniMax Hailuo 02
MiniMax-Hailuo-02
A foundational AI video model with top-tier physics simulation and temporal consistency. Excels at dynamic scenes and clear subject rendering, supporting diverse art styles. Ideal for reliable, high-quality video generation across creative and commercial projects.
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
Vidu Q4 Preview
viduq4-preview
Next-gen flagship video model preview from Shengshu Technology, focused on expressive character performance, cinematic camera work, and complex VFX . Supports up to 15 reference images (characters, wardrobe, props, scenes) and 3 audio references for voice consistency . Generates up to 16-second clips at 540p–4K with 10-bit color depth
Seedance 2.5
dreamina-seedance-2-5-260628
ByteDance's latest flagship video generation model, built for longer-form storytelling and production-ready output. Generates up to 30 seconds of continuous, cinematic video with native audio sync in a single pass . Accepts up to 50 multimodal references (images, videos, audio, character sheets, storyboards) for precise scene, character, and motion consistency . Features localized region editing to fix specific areas without full regeneration……
Wan 3.0
wan3.0-video
Wan3.0-Video is an all-in-one video generation model unified support for multiple creative capabilities, including reference, editing, replication, and driving. It generates videos up to 30 seconds with omni-modal reference, and can parse files, web pages and complex images. With production-grade character consistency and lifelike visuals and sound, it delivers an immersive audiovisual experience.
Seedance 2.0 Mini
dreamina-seedance-2-0-mini-260615
Lightweight, cost-efficient video model from ByteDance, optimized for speed and high-volume content creation. Supports text-to-video, image-to-video, and reference-based generation with up to 12 references (6 images, 3 audio, 3 video). Delivers faster generation and lower credit consumption than Seedance 2.0, with strong motion quality and character consistency. Ideal for social media content, product videos, AI short dramas, and rapid creative iteration
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with MiniMax H3 Today
Create an account in seconds to receive 100 free credits and start generating immediately. No credit card or upfront contract required.