Qwen3 Coder Plus / 채팅
Powered by Qwen3, this is a powerful Coding Agent that excels in tool calling and environment interaction to achieve autonomous programming. It combines outstanding coding proficiency with versatile general-purpose abilities.
Playground Chat
AI 모델과 대화를 시작하세요. 무엇이든 질문할 수 있습니다.
AI가 생성한 응답의 정확성은 다를 수 있습니다.
Qwen 3.7 PlusHigh-Speed Enterprise Intelligence & Tool Calling Engine
Qwen 3.7 Plus delivers the sweet spot of high token throughput, sub-second latency, and advanced multi-tool calling across a 128,000 token context window—tailored for demanding enterprise production systems.
Key Architectural Highlights of Qwen 3.7 Plus
Engineered for high-volume customer facing workloads, low-latency streaming agents, and cost-effective operations.
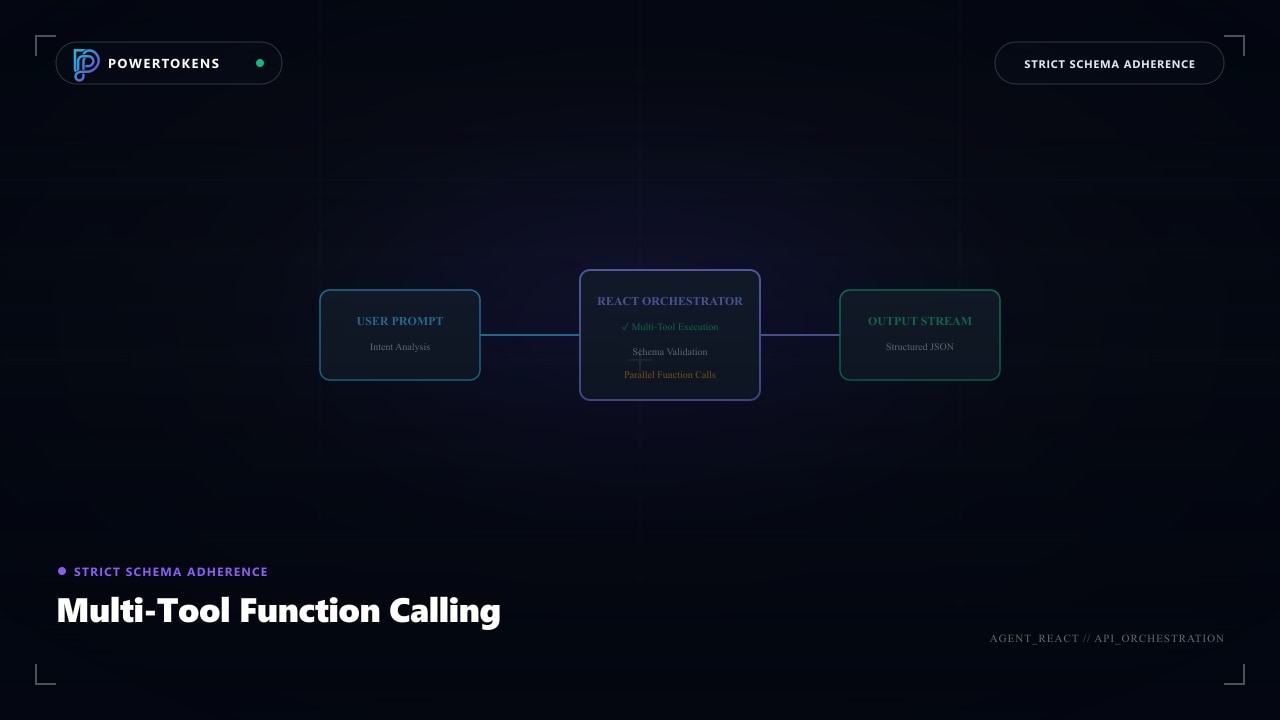
ReAct Multi-Tool Calling & Schema Execution
Trained on complex real-world function orchestration schemas. Accurately invokes APIs, parses SQL databases, and queries external search engines with strict JSON formatting.
High-Throughput Streaming Compute & Instant TTFT
Delivers sustained high generation speed with minimal time-to-first-token jitter, keeping conversational response times snappy even during peak enterprise traffic loads.
Production & Industry Use Cases
Proven performance in high-frequency production deployments and enterprise automation workflows.
High-Concurrency Conversational AI
Power enterprise customer support bots, virtual concierge assistants, and voice agents with instantaneous sub-second response times and natural tone.
Real-Time API & Webhook Orchestration
Ingest continuous telemetry, parse inbound webhooks, validate JSON payloads against dynamic schemas, and trigger external microservices reliably.
High-Speed Inline Code Generation
Feed developer IDE autocomplete, continuous code review linters, and synthetic test suite generators with rapid streaming token delivery.
Global Multilingual Localization
Accurately translate, summarize, and adapt technical manuals, legal contracts, and product copy across 50+ languages with consistent terminology.
Multi-Language Integration Code
Production-ready snippets for cURL, Python, Node.js, and Go.
curl -X POST "https://api.powertokens.ai/v1/chat/completions" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen3.7-plus",
    "messages": [
      {
        "role": "system",
        "content": "You are an enterprise data transformation engine. Return validated JSON output."
      },
      {
        "role": "user",
        "content": "Parse this inbound JSON webhook payload and return a validated schema with anomaly flags."
      }
    ],
    "temperature": 0.2,
    "max_completion_tokens": 2048,
    "stream": true
  }'
Technical Specifications & Parameter Reference
Accurately extracted and verified against Qwen 3.7 Plus OpenAI-compatible endpoint specifications.
| Provider & Model ID | Alibaba Cloud (Qwen Team) • qwen3.7-plus |
| API Protocol | OpenAI-Compatible POST /v1/chat/completions |
| Context Window Size | 128,000 Tokens (High-Throughput Window) |
| Max Output Tokens | Up to 8,192 Tokens per response |
| Inference Latency | Sub-second Time-to-First-Token (TTFT) with high TPS |
| Tool Calling Engine | Multi-Tool ReAct execution with native structured outputs |
| Streaming Protocol | Server-Sent Events (SSE) streaming format with low buffer latency |
| Cost-Performance Ratio | Optimized pricing for high-volume enterprise production workloads |
| Recommended Use | High-QPS production APIs, agentic orchestration, real-time chat |
| Enterprise SLA | 99.9% uptime, dedicated burst capacity, zero data retention |
가격 상세
이 모델의 실제 요금은 API 요청에서 전달된 특정 매개변수를 기반으로 동적으로 계산됩니다. 아래는 구체적인 조합과 해당 가격입니다:
| 모달리티 | 입력 크레딧 | 출력 크레딧 | 입력 가격 | 출력 가격 | 암시적 캐시 적중 | 명시적 캐시 적중 | 캐시 생성 |
|---|---|---|---|---|---|---|---|
| 0 - 32K | 1,000/ 1M Tokens | 5,000/ 1M Tokens | $1.000 | $5.000 | $0.200 200/ 1M Tokens | $0.100 100/ 1M Tokens | $1.250 1,250/ 1M Tokens |
| 32K - 128K | 1,800/ 1M Tokens | 9,000/ 1M Tokens | $1.800 | $9.000 | $0.360 360/ 1M Tokens | $0.180 180/ 1M Tokens | $2.250 2,250/ 1M Tokens |
| 128K - 256K | 3,000/ 1M Tokens | 15,000/ 1M Tokens | $3.000 | $15.000 | $0.600 600/ 1M Tokens | $0.300 300/ 1M Tokens | $3.750 3,750/ 1M Tokens |
| 256K - 1M | 6,000/ 1M Tokens | 60,000/ 1M Tokens | $6.000 | $60.000 | $1.200 1,200/ 1M Tokens | $0.600 600/ 1M Tokens | $7.500 7,500/ 1M Tokens |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Qwen3.8 Flash
qwen3.8-flash
Alibaba's cost-efficient multimodal reasoning model. Supports text, image, and video inputs with text output. Features a native 1M-token context window for long documents, codebases, and agentic workflows. Excels in coding assistance, desktop interaction, chart analysis, and long-video understanding. Compatible with OpenAI/Anthropic protocols for seamless integration
Qwen3 Max
qwen3-max
Compared with the September 23, 2025 version, the newly upgraded Qwen-3 Max seamlessly integrates thinking and non-thinking modes, bringing an all-round obvious performance boost. Its thinking mode supports web search, web content extraction and code interpreter. It can conduct in-depth logical reasoning and call external tools to solve intricate problems more precisely
Qwen3.6 Plus
qwen3.6-plus
The Qwen3.6 native vision-language Plus series models demonstrate exceptional performance on par with the current state-of-the-art models, with a significant improvement in overall results compared to the 3.5 series. The models have been markedly enhanced in code-related capabilities such as agentic coding, front-end programming, and Vibe coding, as well as in multi-modal general object recognition, OCR, and object localization.
Qwen3.5 Flash
qwen3.5-flash
The Qwen3.5 native vision-language Flash models are built on a hybrid architecture that integrates a linear attention mechanism with a sparse mixture-of-experts model, achieving higher inference efficiency. Compared to the 3 series, these models deliver a leap forward in performance for both pure text and multimodal tasks, offering fast response times while balancing inference speed and overall performance.
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
GLM-5.3
glm-5.3
Zhipu AI's flagship text model optimized for complex software engineering and long-horizon Agent tasks. Features a 1M-token context window with mandatory reasoning (3 levels: low/high/max). Coding capability improved 50% over GLM-5.2 on Z.ai Code Bench; scores SOTA on Terminal Bench 3.0. Excels in cybersecurity tasks (cyber vulnerability discovery)
GLM-5.2
glm-5.2
Flagship text model purpose-built for long-horizon agentic workflows. Features a 1M context window supporting project-level engineering in a single session. Excels at autonomous coding: can complete development, testing, and multi-platform deployment from a single prompt. Top open-weight model per Artificial Analysis; #1 globally on Code Arena. MIT-licensed and Day-0 optimized for domestic AI chips
GLM-5
glm-5
GLM-5 is Z.ai’s flagship open-source foundation model engineered for complex systems design and long-horizon agent workflows. Built for expert developers, it delivers production-grade performance on large-scale programming tasks, rivaling leading closed-source models. With advanced agentic planning, deep backend reasoning, and iterative self-correction, GLM-5 moves beyond code generation to full-system construction and autonomous execution.
MiniMax M3
MiniMax-M3
Flagship multimodal foundation model supporting text, image, and video inputs with text output. Features a 1M-token context window via MiniMax Sparse Attention (MSA), cutting per-token compute to ~1/20 of previous gen at full context. Excels at long-horizon agentic work, coding, and tool use. Native multimodal training from step zero ensures deep semantic alignment. Scores 59.0% on SWE-Bench Pro and 83.5 on BrowseComp, surpassing Opus 4.7
Frequently Asked Questions
Comprehensive answers regarding Qwen 3.7 Plus integration, high-QPS limits, and streaming stability.
Start Building with Qwen 3.7 Plus Today
Create an account in seconds to receive 100 free credits and start generating immediately. No credit card or upfront contract required.