MiniMax-H3

MiniMax H3 / テキストから動画

Commercial
ID: MiniMax-H3

Open-weight general-purpose multimodal video model. Unifies text, image, video, and audio understanding in a single context window, generating up to 2K resolution, 15-second clips with native stereo audio at 24fps. Supports multimodal reference inputs: up to 9 images, 3 videos, and 3 audio clips (12 total references) per generation. Features first-frame, last-frame, and full reference modes with conversational editing capabilities.
モデルタイプ:
料金$0.08/ Second(80 クレジット)
Create a 6-second photorealistic Diwali portrait video in horizontal 16:9 format. Locked-off frontal eye-level camera, one continuous shot, framing the woman from above her head to just below her waist and skirt waistband. Center the portrait within approximately the middle 42% of the frame width. Preserve natural body proportions. Fill both sides with a seamless continuation of the festive backdrop: no black bars, borders, panel seams, or hard vertical color division. Do not stretch the woman. HIGHEST PRIORITY: TWO SNAPS, THREE COLOR STATES Begin with the ENTIRE frame in grayscale. After the FIRST snap, reveal color in the backdrop, lettering, lamp, flame, and complexion, while the blouse, skirt waistband, and dupatta stay muted gray-brown. Only AFTER the SECOND snap may the clothing turn vivid magenta. The action must trigger the color change, never follow it. All colors described below refer to the revealed appearance; the opening renders everything in grayscale. CHARACTER A young woman aged approximately 18-20, with warm light-brown skin, a soft oval face, naturally full cheeks, a gentle jawline, a small rounded chin, bright deep-brown almond-shaped eyes, natural thick arched eyebrows, a straight softly defined nose, and full nude-rose lips. Fine, realistic skin texture and fresh, light makeup: subtle blush, a sheer base, and fine eyeliner. No heavy smoky makeup, dark lipstick, hollow cheeks, or strong cheekbone contouring. She begins calm and curious and only develops her delighted smile at the end. Maintain this combination of complexion, facial features, and dark hair rather than introducing a different character design. A slender, graceful, naturally proportioned build, slim arms, softly defined shoulders, a defined waist, and a flat midriff. Thick, airy, near-black dark-brown hair with a slightly off-center part, long face-framing layers, and large loose waves flowing over the shoulders and chest toward the waist. Avoid flat roots or rigid, uniformly arranged curls. Round pale pearl-like earrings, three fine gold necklaces including a small round pendant, and delicate gold chains and bangles on both wrists. WARDROBE AND LAMP A fitted rose-pink to deep-magenta Indian festive cropped blouse with a curved scoop neckline, sleeves ending near the elbows, and an exposed waist. Small gold floral embroidery covers the blouse and matching high-waisted skirt. Fine gold neckline trim and wide gold vine-pattern sleeve borders. Show the skirt waistband and upper portion without broad vertical gold panels. A sheer magenta dupatta with small gold motifs and a wide embroidered border drapes over the shoulder and arm on the VIEWER'S LEFT. Do not make the blouse sleeveless or move the dupatta to the right. Color changes do not alter the garment construction or patterns. One palm-sized, shallow reddish-brown terracotta diya with a rounded bowl, a finely ribbed rim, and a low base, not a deep pedestal bowl. Support it on cupped palms below the chest, near the waist, rather than pinching it high against the chest. One wick and one flame, already burning in the first frame and gently flickering throughout. BACKGROUND A vivid, luminous festive setting: bright amber-orange and gold on the left, rich blue and blue-teal on the right, blending naturally through the center rather than forming two flat panels. Small star-like lights drift slowly and twinkle behind the woman and across both side areas, with gentle brightness changes and a few larger soft bokeh lights. This subtle motion continues throughout the entire background. Keep lights off her face; no fireworks, dense flying debris, or outer-space star field. Use pleasing spatial depth. Large gold uppercase serif lettering spelling exactly "DIVALI" sits above and behind her head within the central portrait area, with subtle dimensional thickness and partial occlusion by her hair. Do not repeat the lettering into the side areas. All lights, lettering, and background are grayscale at first and gain color only after the first snap. 0-1.2 SECONDS The entire frame is monochrome, including the background, lettering, lamp, and flame. She cups the lamp, slightly tilts her head, and looks at the camera with naturally parted lips. The hand on the VIEWER'S RIGHT rises beside her face. Around 1.2 seconds, its middle finger presses against the thumb, then quickly slips off and strikes toward the palm: one crisp, brief snap. The hand on the viewer's left keeps supporting the lamp. 1.2-4.25 SECONDS After the first snap, the full backdrop gradually reveals amber-gold and blue, the moving lights become gold-white, the letters become gold, and the lamp and flame gain color. Her face and hands gradually acquire natural skin tones. The blouse, waistband, and dupatta remain strictly muted gray-brown until the second snap: do not turn them pink around 2 seconds. She lowers the raised hand, cups the lamp with both hands, looks down at its flame with curiosity, and leans forward slightly. Then she looks back toward the camera and raises the hand on the viewer's right again. AROUND 4.25 SECONDS Perform the second crisp thumb-and-middle-finger snap on the VIEWER'S RIGHT. Show a brief finger release, not a prolonged pinching pose. Only AFTER this snap, around 4.3-4.8 seconds, transform the gray-brown blouse, waistband, and dupatta into vivid rose pink and deep magenta, with brighter gold embroidery. The already-colored backdrop continues moving naturally and never returns to grayscale. 4.8-6 SECONDS Lower the raised hand and hold the lamp securely with both palms again. Facing the camera, she now develops a bright, natural, teeth-showing smile with a small relaxed head adjustment. End in full color. Maintain the described youthful features, slender proportions, airy waves, embroidered sleeved blouse, left-side dupatta, and shallow diya throughout. Exactly one woman, one lamp, one flame, and two snaps. No mirrored hand switching, cuts, zoom, camera movement, extra people or limbs, white flashes, magical beams, added captions, or logos. Keep only the background lettering "DIVALI". The entire 16:9 frame has a continuous animated background with no black bars.
Input Prompt
6195
動画生成
合計 1 件の結果
MiniMax H3 Hero Visual
MiniMax H3 • Multimodal Reference Video

MiniMax H35-Mode Cinematic Video with 2K Output

MiniMax H3 is a multimodal video foundation model with five generation modes — text, image, end-frame, start-and-end-frame, and reference conditioning — plus native 2K resolution and up to 15-second clips.

5 Generation Modes
768P / 2K Native Resolution
4–15 Second Clips
Reference Conditioning + 6 Ratios
ByteDance Seed Foundation Architecture
Commercial License & Enterprise SLA

At a Glance

5
Generation Modes
Text → Reference
2K
Max Resolution
Also 768P
4–15s
Clip Duration
1-second steps
6
Aspect Ratios
Plus adaptive
Capability Highlights

Multimodal Video Architecture

One model for every conditioning path — from pure text to multi-reference cinematography.

Five Conditioning Modes

Text-to-video, image-to-video, end-frame, start-and-end-frame, and multimodal reference-to-video — switch modes without changing providers.
T2VI2VEnd FrameReference
Five modes montage
2K cinema still

Native 2K Resolution

Ship 768P for drafts and social, or promote hero placements to 2K without a separate upscaler pass.

768P2KHero Ready

Start & End Frame Bridges

Land exactly on a target end frame for match cuts, product morphs, and seamless scene transitions.
Start FrameEnd FrameMatch Cut
Frame bridge concept
Multi ratio canvas

Cinematic Ratio Suite

Text-to-video supports 21:9, 16:9, 4:3, 1:1, 3:4, and 9:16; reference mode also allows adaptive framing.

6 Ratios21:9 Ultra-WideAdaptive
How It Works

How It Works

From brief to finished multimodal clip.

01

Pick a Mode

Start from text, a still, an end frame, both frames, or multimodal references.

02

Set Canvas & Length

Choose 768P or 2K, aspect ratio, and 4–15 second duration for the placement.

03

Condition with References

In reference mode, feed stills or motion cues that lock identity and style.

04

Deliver & Chain

Pull the finished clip and bridge into the next shot with end-frame continuity.

H3 Production Domains

Where multimodal control replaces stitched pipelines.

Film

Brand Film Previs

Reference-conditioned previs before full live-action shoots.

Reference
Commerce

Product Morph Ads

End-frame and dual-frame transitions for packshot reveals.

Frame Bridge
Marketing

Ultra-Wide Storytelling

Native 21:9 cinematic boards for hero brand placements.

21:9
Content

Social Vertical Cuts

9:16 clips up to 15 seconds for Reels and TikTok.

9:16
Best Practices

Prompt & Usage Tips

Get cleaner first-pass H3 generations.

Name the mode intent early

If you need a bridge, mention the end composition in the prompt so the model aims for that landing frame.

2K only for heroes

Draft at 768P, promote only final hero placements to 2K to control spend.

Reference with one clear subject

Reference mode is strongest when each image has a single clear job — identity, style, or scene.

Developer Quickstart

H3 Multimodal Quickstart

Submit text or reference-driven clips with native 2K support.

curl -X POST "https://api.powertokens.ai/v1/videos" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "MiniMax-H3",
  "prompt": "Cinematic tracking shot through a neon cyberpunk city in heavy rain.",
  "seconds": "5",
  "size": "1080p",
  "ratio": "16:9",
  "resolution": "2K",
  "duration": 8
}'

Technical Specifications

Confirmed parameters and runtime execution protocols.

Provider & Model ID
MiniMax • MiniMax-H3
Modes
Text-to-video, Image-to-video, End-frame, Start & end frame, Reference-to-video
Resolutions
768P (default) or 2K
Duration
4 to 15 seconds (default 4)
Aspect Ratios (T2V)
21:9, 16:9, 4:3, 1:1, 3:4, 9:16 (default 21:9)
Aspect Ratios (I2V)
Adaptive framing
Reference Mode Ratios
adaptive + 21:9 / 16:9 / 4:3 / 1:1 / 3:4 / 9:16
Billing Unit
Per second of generated video
Tags
Video to Video supported
API Endpoint
POST /v1/videos

料金詳細

このモデルの実際の課金は、API リクエストで渡される特定のパラメータに基づいて動的に計算されます。以下は具体的な組み合わせとそれに対応する料金です:

注: 各リクエストの最初の5枚の入力画像は無料です。それ以降の入力画像は表に表示されている入力価格に基づいて課金されます。

課金ルール:入力動画と出力動画の両方が課金対象となり、動画の秒数単位で計算されます。

768P
画像入力
$0.040(40 / Image)
動画入力
$0.080(80 / Second)
出力
$0.080(80 / Second)
2K
画像入力
$0.040(40 / Image)
動画入力
$0.130(130 / Second)
出力
$0.130(130 / Second)
Same Channel

Models from the Same Channel

Explore complementary models and alternative versions from the same provider channel.
MiniMax-H3-Max
videoCommercial
MiniMax-H3-Max

MiniMax-H3-Max

MiniMax-H3-Max

High-speed video model post-trained by fal.ai on MiniMax H3, optimized for low-latency generation. Ranks #1 in image-to-video (Elo 1,204) and #3 in text-to-video with audio (Elo 1,235) on Artificial Analysis. Generates 5-second 768p video in under 3 seconds (35x throughput vs. H3), enabling real-time streaming, live AI broadcasting, and instant content creation. Supports text-to-video and image-to-video (first/last frame), 5–15s clips, 480p/768p, and native stereo audio
Text to VideoImage to Video
MiniMax Hailuo 2.3 Fast
videoCommercial
MiniMax Hailuo 2.3 Fast

MiniMax Hailuo 2.3 Fast

MiniMax-Hailuo-2.3-Fast

A streamlined AI video model prioritizing speed and cost-efficiency. Generates 6-second 768p videos rapidly with 50% lower batch costs. Maintains solid motion physics and stylization for quick iterations, drafts, and short-form content.
Text to VideoImage to Video
MiniMax Hailuo 2.3
videoCommercial
MiniMax Hailuo 2.3

MiniMax Hailuo 2.3

MiniMax-Hailuo-2.3

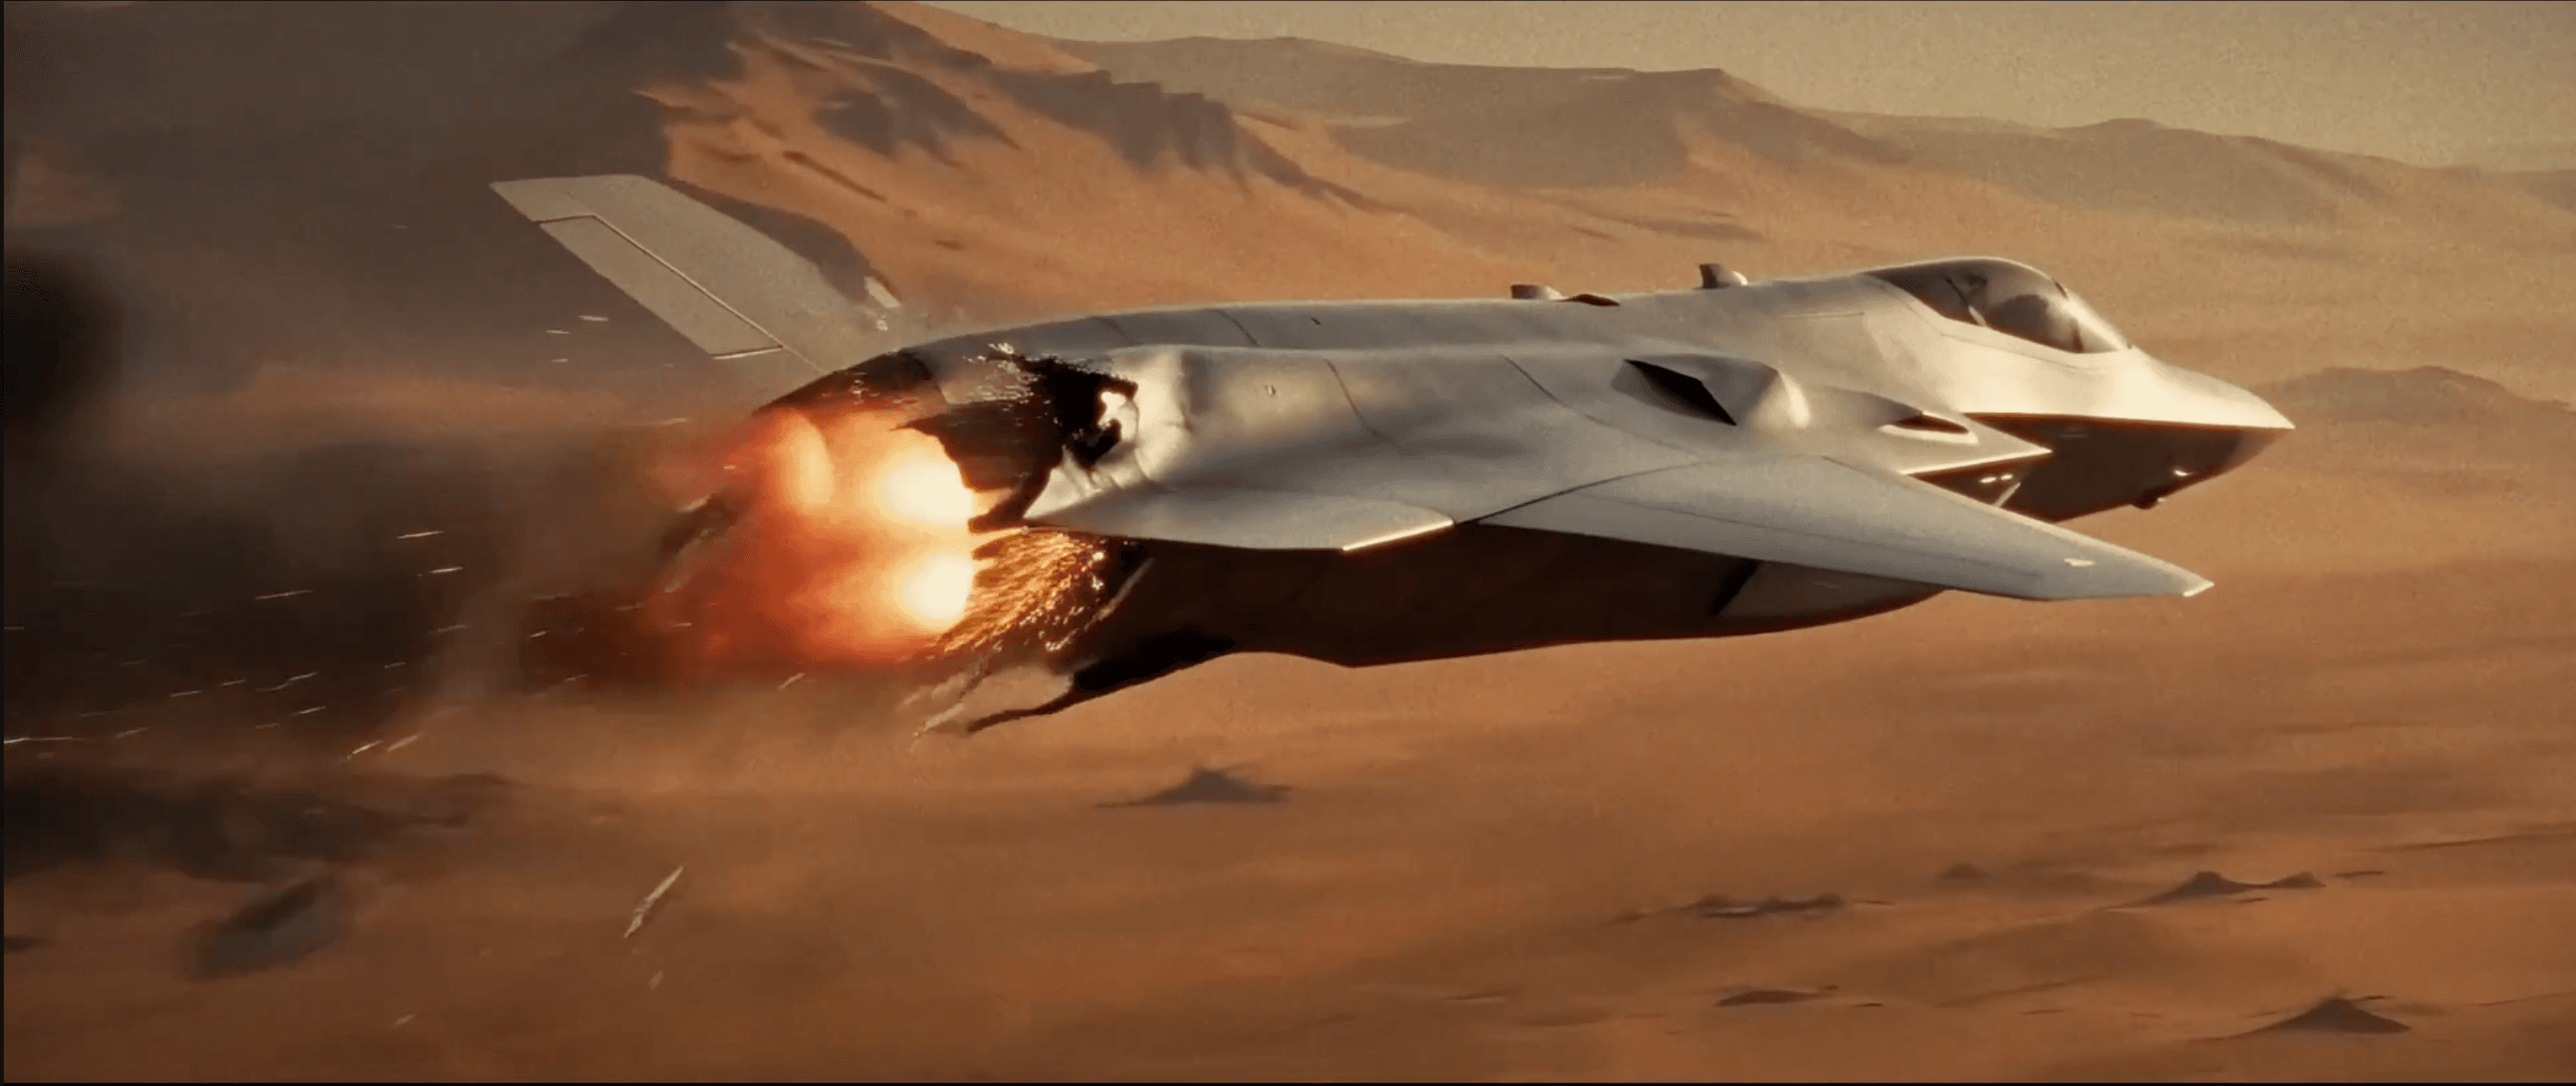
A flagship AI video model delivering breathtaking motion and lifelike emotion. Excels in fluid character movements, cinematic lighting, and multi-style support (anime, ink wash). Produces 1080p, 6/10-second videos with natural micro-expressions for high-fidelity creative work.
Text to VideoImage to Video
MiniMax Hailuo 02
videoCommercial
MiniMax Hailuo 02

MiniMax Hailuo 02

MiniMax-Hailuo-02

A foundational AI video model with top-tier physics simulation and temporal consistency. Excels at dynamic scenes and clear subject rendering, supporting diverse art styles. Ideal for reliable, high-quality video generation across creative and commercial projects.

Text to VideoImage to Video
Ecosystem Models

Recommended Related Models

Explore complementary video and multimodal models with your unified API key.
Browse All Models
Vidu Q4 Preview
videoCommercial
Vidu Q4 Preview

Vidu Q4 Preview

viduq4-preview

Next-gen flagship video model preview from Shengshu Technology, focused on expressive character performance, cinematic camera work, and complex VFX . Supports up to 15 reference images (characters, wardrobe, props, scenes) and 3 audio references for voice consistency . Generates up to 16-second clips at 540p–4K with 10-bit color depth
Text to VideoImage to Video
Seedance 2.5
videoCommercial
Seedance 2.5

Seedance 2.5

dreamina-seedance-2-5-260628

ByteDance's latest flagship video generation model, built for longer-form storytelling and production-ready output. Generates up to 30 seconds of continuous, cinematic video with native audio sync in a single pass . Accepts up to 50 multimodal references (images, videos, audio, character sheets, storyboards) for precise scene, character, and motion consistency . Features localized region editing to fix specific areas without full regeneration……
Text to VideoImage to Video
Wan 3.0
videoCommercial
Wan 3.0

Wan 3.0

wan3.0-video

Wan3.0-Video is an all-in-one video generation model unified support for multiple creative capabilities, including reference, editing, replication, and driving. It generates videos up to 30 seconds with omni-modal reference, and can parse files, web pages and complex images. With production-grade character consistency and lifelike visuals and sound, it delivers an immersive audiovisual experience.
Text to VideoImage to Video
Seedance 2.0 Mini
videoCommercial
Seedance 2.0 Mini

Seedance 2.0 Mini

dreamina-seedance-2-0-mini-260615

Lightweight, cost-efficient video model from ByteDance, optimized for speed and high-volume content creation. Supports text-to-video, image-to-video, and reference-based generation with up to 12 references (6 images, 3 audio, 3 video). Delivers faster generation and lower credit consumption than Seedance 2.0, with strong motion quality and character consistency. Ideal for social media content, product videos, AI short dramas, and rapid creative iteration

Text to VideoImage to Video

Frequently Asked Questions

Everything you need to know before integrating this model.

It supports five conditioning paths in one model: text-to-video, image-to-video, end-frame, start-and-end-frame, and reference-to-video.

Start Building with MiniMax H3 Today

Create an account in seconds to receive free test credits. No upfront payment or long-term contract required.